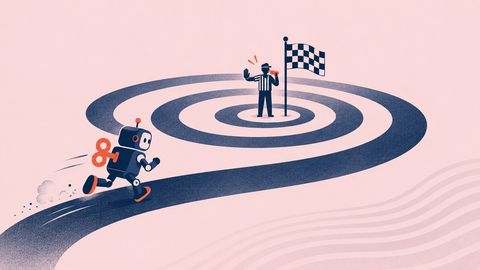
An agentic loop is a job that runs until a checkable goal is met. Nufar Gaspar's rule for knowledge work: a loop only works with "a very boring, very checkable finish line", and if you cannot write one, do not loop. For a freelancer that makes the finish line the product: the goal card, the referee and the final check are what the client pays for. Loops are among the most token-hungry things you can run, so the cost belongs in the quote and in your Betriebsausgaben. A study of BCG consultants shows why the check is not optional.
If your work is judgement, the agent is not going to run it for you overnight. If your work has a finish line you can write down, it might. Most freelance knowledge work is a mix of the two, and the money is in knowing which is which.
That is our reading of a webinar Nathaniel Whittemore published as an episode of The AI Daily Brief on 3 September 2026, with Nufar Gaspar, an AI and agents consultant and trainer, doing most of the explaining. The episode is aimed at corporate knowledge workers and never mentions freelancers. It should have. Every freelancer is a one-person organisation, and Nufar's one-liner is built for that.
"A loop is basically a job, and a graph is an organization." (Nufar Gaspar)
What a loop is, and what it is not
Every agentic tool already runs a loop under the hood: plan, act, check, adjust. The native loop stops when the tool thinks it is done, usually after one polite pass. The loop Nufar talks about is the one where you set the end condition, through a goal or loop command depending on the tool, and it keeps cycling until the condition is met or a cap is hit.
Two distinctions matter. A loop is not a schedule: "A schedule answers the question of when. A loop answers the question of until." And a loop is not for everything. Her list of what makes a task loop-worthy: it is long-running, so one prompt does not get you there; you can check whether the result is good enough; you would like to send it away overnight and come back to a finished result rather than a draft; the best one-shot output was not good enough; and the work has a natural draft-then-improve shape.
Then the line that should be printed above every freelancer's desk:
"Knowledge work only succeeds on loop exactly when you invent a very boring, very checkable finish line. And boring here, by the way, is a compliment." (Nufar Gaspar)
"Two hundred verified data points, each with URL and date" is boring and checkable. "Make it insightful" is neither, and the agent cannot converge on it. Her rule for the second kind: "If your judgment is the actual work and you cannot offload the judgment to a referee, a normal conversation with your agent is the right call, and choosing that is the smart move, not the cop-out."
Which client tasks are loop-worthy
Apply that test to a freelance week and the split is clearer than it looks.
Loop-worthy: a research sweep for a market report with a quota of sources per category; a competitive scan of every named player against the same rubric; a content audit of a client's 400 pages against a written checklist; cleaning a dataset until every row passes a schema; verifying every citation in a deck against its URL; a compliance pass of documents against a numbered list of clauses. All of them have a count, a rubric or a schema the loop can check itself against.
Not loop-worthy: the client's positioning, the recommendation at the end of the report, the difficult email to the CEO, the hiring shortlist, the strategy. Nufar's reason: "Autonomy, at the end of the day, does not have a taste on its own." Those are the tasks the client hired a person for, and they are also the tasks where a confident, wrong output does the most damage.
The research says how much damage. In a field experiment with 758 BCG consultants, Dell'Acqua, Mollick and colleagues found that for tasks inside the model's capability AI users completed 12.2% more tasks, 25.1% faster, with more than 40% higher quality. For a task chosen to sit just outside that capability, AI users were 19 percentage points less likely to produce a correct answer than consultants without AI. The frontier is jagged and you cannot see it from the outside. A loop with a bad finish line runs straight across it, at speed, overnight.
The goal card
Nufar's tool for writing the finish line is a goal card. Her worked example was a token-efficiency playbook, and the card is worth copying as a structure:
- Objective, one line, machine-readable: the definitive playbook on X as of this month.
- Output: a file, a table, a document at a path.
- Done when: at least 200 unique data points, each with URL, date and type; a mix of at least 40 vendor documents, 40 practitioner sources and 20 benchmarks; zero duplicates.
- Optional stages: which gates the agent should pass, if you want to steer the route.
- Fail-safes: a turn cap (she used 30), sandbox only, a time cap.
- A log: ask the agent to say out loud what it is doing and which cycle it is on, so you can watch progress.
The fail-safes are not optional. Her loop went past 200 data points in one run and to 300 in another; the cap of 30 cycles was what stopped it. Her failure modes map neatly onto a freelancer's: runaway spend (no cap), a stuck loop (the task cannot converge), and the sneaky one, "it met the letter of your finish line, but the results are still very bland". That last one, she says, is the goal card's failure, not the loop's.
Anthropic's guidance on building agents, written by Erik Schluntz and Barry Zhang for developers in December 2024, says the same from the other side of the table: "we recommend finding the simplest solution possible, and only increasing complexity when needed", agents are for open-ended problems where you cannot predict the number of steps, and "the autonomous nature of agents means higher costs, and the potential for compounding errors", so test in sandboxed environments with guardrails and let the agent pause for human feedback at checkpoints. That is a goal card in engineering language.
Tokens in the quote and in the books
"Loops are among the most token-hungry executions that you can have with your agentic tools," Nufar warns, and deep-research features "can easily take millions of tokens without batting an eye". For an employee that lands on a corporate invoice. For a freelancer it lands on yours.
Two places to put it. In the books, API and subscription costs for tools you use for client work are expenses caused by the business, which is the one-sentence definition of Betriebsausgaben in § 4 Abs. 4 EStG; keep the invoices per project, and see the Betriebsausgaben checklist and our tax basics for freelancers for the mechanics. In the quote, decide before the project whether compute is a pass-through line or baked into the fixed price, and write which. A loop that costs 40 euros of tokens on a 4,000-euro report is a rounding error; the same loop rerun five times because the finish line was vague is not, and the client should not discover that on the invoice. Our quote template has a line for it. Two freelancers who built their own assistants report what the running costs really were.
Verification is the paid part
Here is the part of the episode that most directly rewrites a freelance offer. After the loop finished, Nufar did not ship the file. She handed it to a fresh-context citation verifier with a bar to check against, sampled ten data points against their real URLs, and only then produced the report. Her reason for the fresh context: models tend to agree with themselves, "like a GPT verifying GPT, odds are it will say that it's correct". And her closing rule: "humans are needed and for the most part superior than the beast. So have human at the right gate."
Translate that into what a client is buying from you. Not the 200 data points; a loop produced those. They are buying the goal card that made the loop produce the right 200, the referee that caught the wrong ones, and your signature under the result. That is the same conclusion our companion piece on Mario Zechner's warning to freelance developers reaches for code: generation is cheap, review is the capacity, and the person who verifies is the one who keeps the client. The difference for knowledge work is that there is no compiler. You have to build the referee yourself, and that, as Nufar says, "is slightly more difficult than for coding, but you can manufacture the referee".
So the offer changes shape. The deliverable is the verified thing. The method section of your proposal names the finish line, the checks and where you sat in the loop. And the price covers the goal card and the verification, the work only you can do, not the cycles, which anyone with the same tool can run.
What to do on Monday
- Take your current project and split the task list in two: checkable finish line, or judgement. Only the first column is a loop candidate.
- Write one goal card for the most repetitive item in the first column, with a quota, a done-when and a turn cap. Run it once in a sandbox folder.
- Add a verification step you do not run in the same context: a fresh session or a second model, with the bar written down, plus a ten-item sample you check by hand.
- Open your quote template and add a line for compute costs, pass-through or included, and a sentence on the checks you run.
- Start a folder for tool invoices per client, so the Betriebsausgaben are there when the tax return comes.
Clients across DACH are starting to ask not whether you use agents but how you check them. A free 9am profile is the place to answer that in one line, so the companies looking for someone who owns the finish line can find you.
This article is an editorial analysis. The episode is embedded above with credit; quotes are from the show's official transcript, lightly cleaned.